This is a SasaDaily hypothetical case.
Not actual customer results published by Anthropic.
Imagine a:
5-person software maintenance studio.
They regularly maintain:
Company websites.
Membership systems.
Admin backends.
APIs.
Internal tools.
The weekly workload is very varied.
It could be:
Searching through an error log.
Changing a database field.
Fixing a bug.
Adding a small feature.
Performing code reviews.
Or suddenly:
Large problems spanning APIs, frontend, and database.
If all tasks immediately used:
The most expensive and powerful model,
It certainly sounds easy.
But by month’s end, you'd notice:
AI works fast—but the costs add up quickly.
The real management challenge isn't "Whether to use AI"
AI coding is already a daily tool.
The true question is:
Which level model is worth using for each task?
So the team stopped requiring:
“Always use the strongest model.”
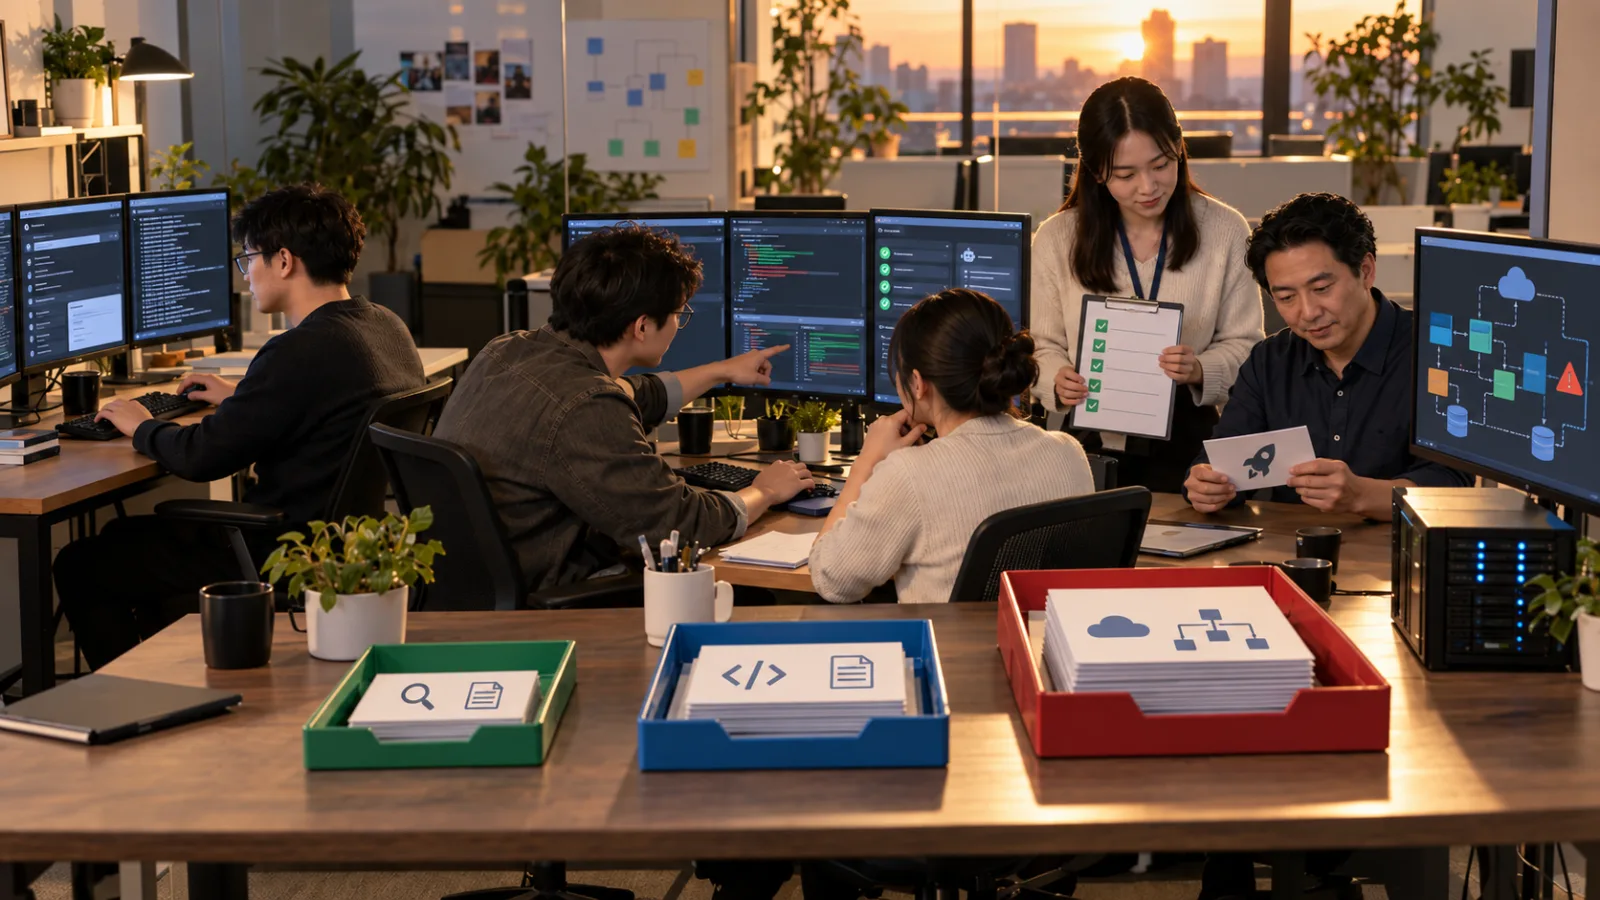
Instead, they split tasks into three tiers.
Tier One: Search Tasks
Examples include:
Locating where a function is defined.
Reading logs.
Finding error codes.
Checking package documentation.
Listing which files reference a certain identifier.
These mainly require:
Finding information.
Heavy reasoning isn’t necessary.
So these tasks go to:
Cheaper smaller models,
or specialized search subagents.
Tier Two: Typical Daily Development
Such as:
Fixing bugs.
Modifying several related files.
Adding small features.
Code review.
Changing APIs following existing patterns.
This tier defaults to:
Claude Opus 5.5.
Tier Three: Truly Stuck Tasks
Examples:
Architectural problems across multiple services.
No existing solutions or patterns.
Tasks requiring long unsupervised work.
Involving multiple subagents.
Or cases where:
Opus 5.5 High has failed twice on the same issue.
Only then do they escalate to:
Claude Fable 5.1.
The real rule isn’t:
“Always start with the hardest model.”
It’s:
“Use the model that’s just good enough.”
The first ticket in the morning: Just searching logs
For example, a client reports:
"Last night the payment page occasionally showed errors."
The engineer doesn’t immediately call Fable 5.1 to:
“Search the entire system.”
Instead, they let a cheaper model handle:
Logs from a specific time yesterday.
Finding:
Error patterns.
Occurrence counts.
Relevant endpoints.
Potential files involved.
Then only returns to the lead engineer:
3–5 key locations that actually need review.
Sometimes if it’s just:
A third-party API timeout,
Even a high-level model may not be needed.
Why not start log searches directly with Opus?
Not because Opus can't do it,
but because:
The real bottleneck at this stage
isn’t complex reasoning,
but rather:
Reading and searching large volumes.
Anthropic’s guidance on Claude Code costs is clear too:
Search,
Lookups,
Log reading subagents
can use cheaper models.
The really needed tasks:
Code editing,
Debugging,
Feature work
should be assigned to Opus 5.5.
This is:
Model routing.
The second ticket: Client requests a small new feature
For example, a client says:
"Add a ‘Pending Manual Confirmation’ status to the admin order page."
This is more than just searching.
It involves changes to:
Database enums.
Backend validation.
API responses.
Frontend badges.
Tests.
The team assigns it to:
Opus 5.5 Medium.
Let the model:
Find all related call sites,
Outline the scope,
Make changes in one go,
Run tests.
Why start with Medium?
Anthropic recommends Opus 5.5 for:
Daily,
Clear scope,
Supervised tasks,
Where Medium is a reasonable starting point.
Because the engineer can watch next to it.
If Claude:
Goes off track,
Misses a dependency,
The engineer can intervene immediately.
No need to pay the highest
Thinking cost upfront for every task.
But "saving thinking" isn’t the highest priority
Suppose after Medium’s edits:
Backend tests pass,
But the engineer finds frontend still sending old fields.
Two possibilities:
First,
There’s no complete end-to-end test.
So add:
Validation,
Tests.
Second,
The model didn’t dig deep enough into dependencies.
Then escalate the effort level to:
High.
Not switch immediately to Fable.
Anthropic also reminds: retries are costly
Because AI agent work isn’t a single request,
but a loop:
Read code.
↓
Use tools.
↓
Check results.
↓
Edit again.
↓
Run tests.
Each additional round sends the previous context again.
So:
“Cheap but wrong three times”
can be more expensive than
“Think a bit more and get it right first time.”
The team tracks:
How much each ticket costs to complete,
not just:
How cheap a single request is.
The third ticket: Complex, multi-system bug
Suppose the problem is:
After a member renews,
The payment service successfully charges,
But:
CRM status doesn’t update,
And emails are sent twice.
This might involve:
Payment webhook,
Queues,
Database transactions,
CRM integration,
Email workers,
Retry logic.
Engineers assign:
Opus 5.5 High
to investigate.
If:
The first attempt finds some issues,
Fixes are made but failure persists,
The second attempt still stalls on the same root cause,
The company has a simple rule:
No third attempt.
Escalate directly to:
Fable 5.1.
Why restrict to "two tries"?
This isn’t a strict technical limit of Anthropic’s,
but a workflow rule.
Anthropic’s Opus 5.5 cost guide also suggests:
If Opus 5.5 High
Fails twice on the same issue,
Upgrade to a stronger model.
Once solved,
Switch back to Opus 5.5.
Because:
Most expensive isn’t always:
The highest-priced model.
Sometimes the real cost is:
Repeated retries with a wrong model.
After fixing the hardest part, don’t keep the whole project on Fable
For example, Fable 5.1 finds:
A conflict between queue retry
and webhook idempotency.
The root cause is found.
Now it’s just:
Changing three files,
Adding tests,
Organizing the PR.
Then switch back to Opus 5.5.
Don’t continue using the most expensive model for all subsequent:
Renaming,
Tests,
Documentation.
This core principle is:
Escalate → Solve → Step Down.
QA no longer just asks “Did AI say it’s done?”
After the model finishes editing,
There must be:
Verifiable evidence.
Like:
Unit tests,
Integration tests,
Builds,
Linting,
API tests.
This company’s policy is:
No test evidence,
No human review.
Because:
AI saying:
Done
is not verification.
Allowing AI to run tests itself can save money
It may seem that:
Running tests again
Costs tokens and turns,
But if a test immediately fails after the first incorrect change,
The model can fix it on the spot.
Better than:
AI claims it’s done,
Someone finds an error the next day,
Starts a new session,
Reloads context,
Re-explains the issue.
Usually more cost-effective.
So:
Verification isn’t wasteful.
Not verifying leads to:
Redoing,
which can be more expensive.
Final checkpoint: Human decides merges
Even if:
Opus 5.5 code review shows no issues,
Tests pass,
QA passes,
The company still doesn’t let AI:
Automatically merge to production branch.
Engineers confirm:
Which files were changed?
Is the scope beyond the original ticket?
Are migrations risky?
How to roll back?
Has requested functionality been silently expanded?
Finally:
Human merges.
Production deploys also require human approval
Before deploy, confirm:
Backups,
Migration windows,
Environment,
Monitoring,
Rollback plans,
Acceptable downtime for clients.
Because:
Correct code
and:
Ready for production
are separate issues.
AI helps:
Create deployment checklists,
Summarize changes,
Generate rollback drafts,
But:
Human approval is still needed to press deploy.
What the company tracks daily isn’t token price
After each ticket completes,
The team notes:
Which model was used,
Effort level,
Number of turns,
Retries,
Human review time,
Final approval status,
and
Estimated overall cost.
The true KPI is:
Cost per completed ticket.
Not:
Cost per million tokens.
Suppose 30 tickets per week
Just a SasaDaily hypothetical calculation.
If the studio receives 30 technical tickets weekly,
Of which:
12 are search/log/lookup,
14 are regular bug/feature/review,
4 are more complex.
If before all 30 used the highest-level model,
Assuming model costs about $150 per week.
Now they switch to:
12 simple tasks on low-cost models,
14 on Opus 5.5,
4 on Opus 5.5 High,
Only the few truly unresolved issues get Fable.
Assuming weekly AI costs drop to:
$95.
Saving about:
$55 per week.
About:
$220 per month.
This is just a:
Demonstration calculation,
Not Anthropic customer results.
If human review takes longer, $220 savings don’t matter
If cheaper models cause:
5 extra hours of manual fixes weekly,
The $220 AI savings
May not translate to overall savings.
So the company also tracks:
Human review time.
For example before introduction,
Average review was 20 minutes per ticket.
Afterwards,
It’s 15 minutes.
That’s real improvement.
If instead it goes to:
30 minutes,
That means:
Model routing
is set too low.
The biggest mistake is shifting costs to engineers to save on AI
AI bills are easy to see.
Engineer time is often overlooked.
For example:
A small model saves $0.50.
But a senior engineer
Spends 20 minutes
Fixing its mistakes.
That $0.50 saving
Becomes meaningless.
So this company compares:
AI cost
+
Human review time
+
Retries
+
Failure risk.
This is the true ROI.
Why is Opus 5.5 suited for the middle tier?
Anthropic positions Opus 5.5 roughly here.
Officially, it has:
Input/output token prices
20% lower than Opus 5,
Cache read cost
60% lower,
Typical workloads
Estimated cost reduction of about 40%.
Meanwhile, Anthropic recommends it as:
The main model for daily feature work,
Debugging,
and code review tasks under supervision.
So it’s neither the cheapest model,
nor the highest-level model for every case,
but rather:
The daily workhorse.
Fable 5.1 comes in only when "problem matters more than token price"
Examples:
Weekend migrations.
Large architectural refactors.
Hours of unsupervised work.
Multiple subagents involved.
Highly unfamiliar problems.
Here:
The cost of failure
May far exceed
Model cost.
That’s when it’s worth:
Paying more.
This is actually similar to how companies manage people.
Not every task
Goes to the most senior staff,
But big exceptions
Can escalate quickly.
The team even checks upgrade cases only once per week
On Fridays they review:
Which tickets escalated from Opus to Fable,
and for what reasons.
If out of 30 per week,
20 get escalated,
That may not mean:
“Fable is too strong.”
But could indicate:
Opus 5.5 isn’t fit for this workload.
Or:
Task scopes are poorly defined,
Tests are incomplete,
Context is insufficient,
or the workflow is flawed.
Conversely,
If no upgrades happen all month,
They question:
Whether this expensive escalation path is even necessary.
Minimal adoption doesn’t require revamping the whole engineering team
If a small company already uses Claude Code,
Don’t build on day one:
Complex routers,
Dashboards,
Automatic cost allocation.
Minimal testing can be as short as:
One week.
Pick three task types:
Search,
Daily coding,
Hard problems.
Assign:
Search → small models.
Daily → Opus 5.5 Medium.
Hard → Opus 5.5 High.
If High fails twice:
→ Fable 5.1.
Then track:
Completion rates,
Turns,
Retries,
Review time,
Estimated cost.
After one week decide:
Does this tiered workload strategy bring value?
This case’s real savings isn’t just "the model got cheaper"
Claude Opus 5.5 is indeed cheaper.
But if the company still:
Uses one model for all tasks,
Runs all tasks at highest effort,
Retries repeatedly on failure,
Uses the highest-level model even for searches,
Has no tests,
No human gate,
Then:
The 20% cheaper model
Just makes an unreasonable workflow
Run slightly cheaper.
The real improvement is to:
Classify tasks.
Simple tasks:
Don’t over-allocate resources.
Normal tasks:
Use the main model.
Hard problems:
Quickly escalate.
After completion:
Step back down.
When AI truly enters enterprises,
Cost management increasingly resembles:
Human resource allocation,
Not:
“Give everything to the strongest guy.”
But:
“Match task needs with just the right capability.”
If you want to know which parts of your work are best suited for AI first, type the word “workflow” in comments.
Today, grow with AI a bit more.
Learn one AI tip daily.
Save a bit of time every day.
Improve your skills daily.
SasaDaily, growing with you.