A 5-person market intelligence team
tracks the following daily:
competitor official websites,
pricing pages,
release notes,
official blogs,
and public industry data.
The biggest challenge in the past was not "not understanding" the content.
Rather, it was:
having to reopen the same batch of sites every day to see if anything changed.
So naturally, the team thought:
"Why not assign AI Agents to check all of these daily for us?"
This approach isn’t wrong.
The problem is,
if your instruction is only:
"Track all 20 websites daily and notify me if there are changes."
you’re really only specifying:
when the task is considered complete.
But you haven’t defined:
how much activity the Agent is allowed to perform on external websites to complete the task.
This case demonstrates a safer approach:
Set source → request limits → stop when exceeded.
This is a Hypothetical SasaDaily Case Study
Let’s be clear:
The 5-person team,
20 websites,
and request budgets
here are all hypothetical examples to illustrate the workflow.
This is not a published client result from an actual company implementation,
nor does following it guarantee a specific time saving.
The real proof
comes from a recent Wikimedia event,
which is discussed later.
What did the team originally do every day?
Assume this is a small market intelligence studio serving B2B clients.
5 people track 20 fixed sources every day:
5 competitor product pages,
5 competitor pricing pages,
5 sets of release notes or official blogs,
and 5 government or industry public data sources.
The real need is not:
to re-read all content daily,
but simply to know:
"What has changed from yesterday to today?"
For example:
Price changes.
Plan name updates.
New feature releases.
API terms updated.
Discontinuation of a service.
New regulatory announcements.
These are what analysts should spend time on.
Where is AI best applied first?
Not by:
"AI does full market strategy for me."
Start with the most repetitive step:
Periodically checking fixed sources to identify changes.
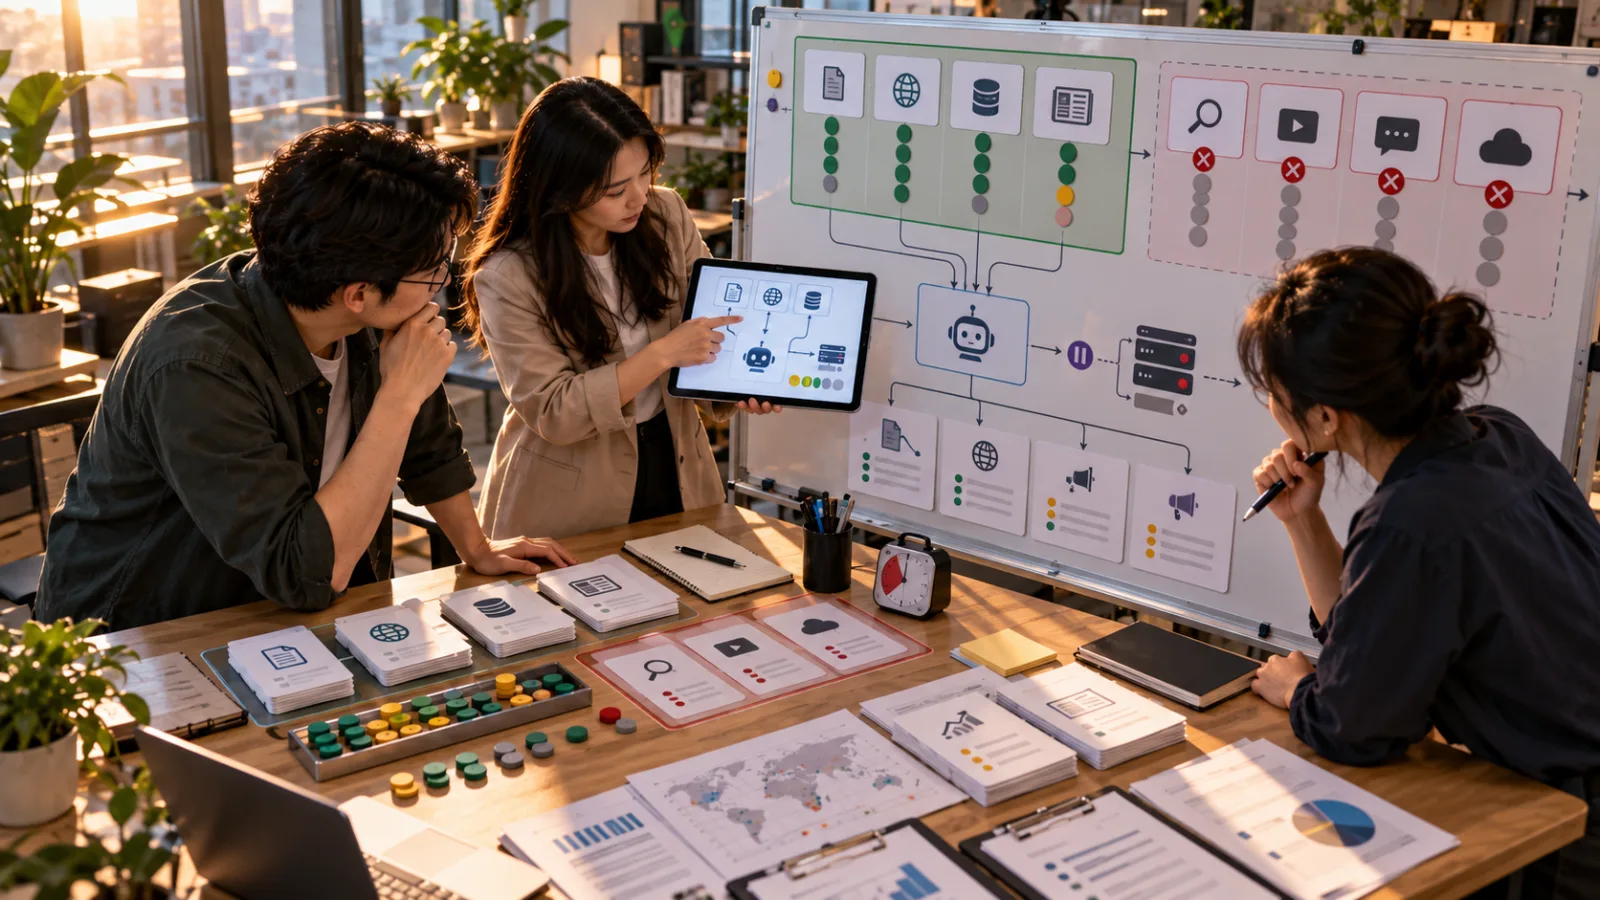
An ideal workflow might be:
Fixed sources →
fetch latest versions →
compare against previous snapshots →
filter only actual changes →
generate a change digest →
then human review to decide what to follow up.
This suits AI well because it’s:
high-frequency,
repetitive,
and can be verified.
However, what’s often overlooked is:
how the Agent acquires this data.
First layer: Restrict Agent’s sources, no unlimited expansion
If the task is to:
track 20 fixed sources,
then first set a:
source allowlist.
Only these 20 sources are monitored daily.
Don’t start with an instruction like:
"Follow any relevant links you find on your own."
because that quickly expands work scope.
A single release note may contain:
10 links,
each leading to 20 related pages.
If the Agent interprets:
"I want to be as complete as possible"
as,
"Follow every link,"
20 sources could quickly turn into hundreds or thousands of requests.
So the first control is:
where the AI is permitted to go.
Second layer: Set a request budget per source
Next, don’t only set:
how often the agent runs,
but also a limit on:
how many requests can be made per source each time.
For example, this hypothetical case might test:
a maximum of 5 pages fetched per source per cycle.
20 sources means,
no more than 100 fetches per overall run.
This isn’t a universal rule online,
nor does it imply:
"100 requests are definitely safe."
It’s simply:
a hard limit set by the team for this workflow.
The actual acceptable request rate
should depend on each website’s:
terms of use,
robots.txt rules,
official API documentation,
and rate limits.
The key point is not the number itself,
but:
that there must be a defined number.
Why not just say "don’t request too much"?
Because for the Agent,
"too much"
has no clear endpoint.
But:
"a maximum of 100 requests this cycle"
does.
Therefore, in a formal workflow,
avoid vague terms like:
"Use the website responsibly."
Instead, apply clearly measurable conditions.
For example:
Maximum 20 sources.
Maximum 5 pages per source.
No repeated fetches on the same URL during a cycle.
Prioritize comparing with existing snapshots.
If the budget is exceeded:
stop and do not increase the limit automatically.
This is true control.
Third layer: When encountering HTTP 429, don’t instruct the Agent to bypass
HTTP 429 means:
Too Many Requests.
Simply put:
The website is telling you:
"You’re sending too many requests right now."
The most dangerous Agent instruction then is:
"Complete the job at all costs."
Because AI might try to:
switch endpoints?
change scraping methods?
use other proxies?
reopen connections?
retry after a second?
But from the website’s perspective,
the message is clear:
Slow down.
So the workflow can be defined to:
on receiving 429 →
read Retry-After header →
wait →
retry according to rules.
If retries continuously fail beyond a set threshold:
stop.
Don’t let the Agent keep trying to find workarounds.
Same applies for 503 — worth stopping too
503 usually means:
Service Unavailable,
indicating the system temporarily can’t process the request.
In this case, the Agent shouldn’t:
increase retry frequency due to failure.
A better approach is:
Backoff.
Wait a little after the first failure.
If it still fails, wait longer.
After reaching retry limits:
record the "no data acquired" event.
This approach is much more mature than forcing a full data fetch.
In market research,
it's generally safer to miss one data source a day than to overload a competitor’s website.
Proof: Wikimedia recently faced this issue
This is not just theoretical:
"Agents can send too many requests."
On October 5, Wikimedia Foundation published an investigation.
It found activity suspected to come from OpenAI Agents caused
millions of automated requests
to Wikimedia’s public APIs,
fetching
millions of pages,
and sending
hundreds of thousands of queries
to the Wikidata Query Service.
Wikimedia concluded this traffic
likely contributed to a partial outage of the Wikidata Query Service in May this year.
Note:
It is "likely."
Wikimedia did not claim with full certainty that the outage was entirely caused by OpenAI Agents.
But this incident clearly demonstrates:
even agents that aren’t stealing data can create real costs due to scale.
Wikimedia provides clear bot usage guidelines
Wikimedia’s official API documentation now explicitly requires that
automated clients be identifiable.
For example, by including a meaningful:
User-Agent header
that contains:
tool name,
version,
and contact info.
The reason is simple:
If your bot misbehaves,
site administrators at least know:
which program it belongs to.
Instead of seeing large amounts of unknown traffic.
They even specify concurrent request limits
Wikimedia’s new 2026 API rate limit documentation
recommends clients keep
concurrent requests at 3 or fewer.
It also requires:
respect for the Retry-After header when receiving 429 Too Many Requests.
This "3" is Wikimedia’s own current rule,
not a universal number.
Other sites may have limits of:
1,
10,
100,
or may forbid automated scraping entirely.
So don’t translate:
"Wikimedia allows 3 parallel requests"
into:
"My agent runs 3 parallel requests everywhere."
The real approach is:
each source reads and follows its own rules.
Use official APIs first if available
This is another key rule small teams should adopt.
When the Agent wants data, the order should be:
official API →
RSS/feed →
official bulk download →
then web pages.
Not:
just open a browser and reload every page every time.
APIs usually make it easier to know:
rate limits,
data format,
authorization,
and error responses.
For example, Wikimedia even reminds users:
large data needs aren’t always suited for repeated Action API calls,
and sometimes one should use official bulk data instead.
This is a typical example of:
don’t make the agent scrape web pages just because it can.
What if the site explicitly forbids automation?
Then don’t do it.
This boundary is the most important in this case.
A website’s content may be publicly accessible,
but that doesn’t mean:
any form of automation,
any frequency,
or any commercial use
is automatically permitted.
Before going live, verify at least:
terms of service,
robots / bot policies,
API policies,
data licenses,
and rate limits.
If the source forbids automated access,
the Agent shouldn’t treat:
"finding an alternative scraping method"
as a success.
Instead,
"this source requires manual handling"
should be the correct result.
What work still needs human involvement?
This workflow does not mean:
AI studies everything daily
and the boss can ignore it all.
A better division of labor is:
AI responsible for
checking at fixed times,
comparing yesterday’s data with today’s,
filtering out unchanged pages,
assembling a list of real changes,
including sources,
and recording any fetch failures.
Humans responsible for
judging whether changes are truly important,
verifying numbers and terms,
deciding whether to notify clients,
conducting competitive strategy analysis,
and determining whether to add new sources.
Especially:
don’t let the Agent add new websites to monitored lists automatically.
Any changes to the source allowlist must be approved by humans.
The real KPI is not "how many pages the Agent fetched"
If you only measure:
number of fetches,
more looks like better effort.
But the real goal is:
whether analysts find valuable changes faster.
So this hypothetical team should track:
how many meaningful changes are reported daily,
how many are judged valuable by analysts,
the time humans spend validating,
the number of missed important updates,
the amount of false alarms,
and whether rate limits, blocks, or abnormal traffic occur.
Success is not:
AI fetching 100,000 pages,
but rather:
finding the 10 truly important items at reasonable cost and external system load.
A simple workflow you can start using immediately
If you want to test tomorrow,
don’t build a complex system yet.
Just write down these four points:
1. Sources
Which websites/APIs are allowed for checking this time?
2. Request Budget
Maximum requests per site per cycle?
Maximum requests for the entire task?
3. Backoff
How to wait on 429/503 errors?
Maximum retry attempts?
4. Stop
Stop and escalate to humans if:
budget is exceeded,
source forbids automation,
or consecutive failures occur.
Then let the Agent:
fetch →
compare →
summarize →
report.
Why is this more important than "track my competitors daily"?
Because the maturity of AI workflows
is not measured by whether it can complete a single task,
but by:
whether it maintains these boundaries after running 100 cycles daily.
Agents fit for corporate use must not have:
only goals,
but also
budgets,
boundaries,
and stop conditions.
This is the key lesson enterprises should learn from the Wikimedia incident.
If you want to know which step in your work is best handed to AI first, leave a comment with the word "workflow," and I can help identify where to start.
Recommended Reading
AI Quick Guide|2026/08/01: Before Letting AI Agents Work, Clearly Define "When to Stop" Conditions