After OpenAI recently disclosed a large-scale Model Distillation incident, a common question emerges:
If I pay to use ChatGPT or Claude,
and the platform says:
The output belongs to me.
Does that mean I can collect all those answers extensively,
and then use them to train my own AI model?
Not necessarily.
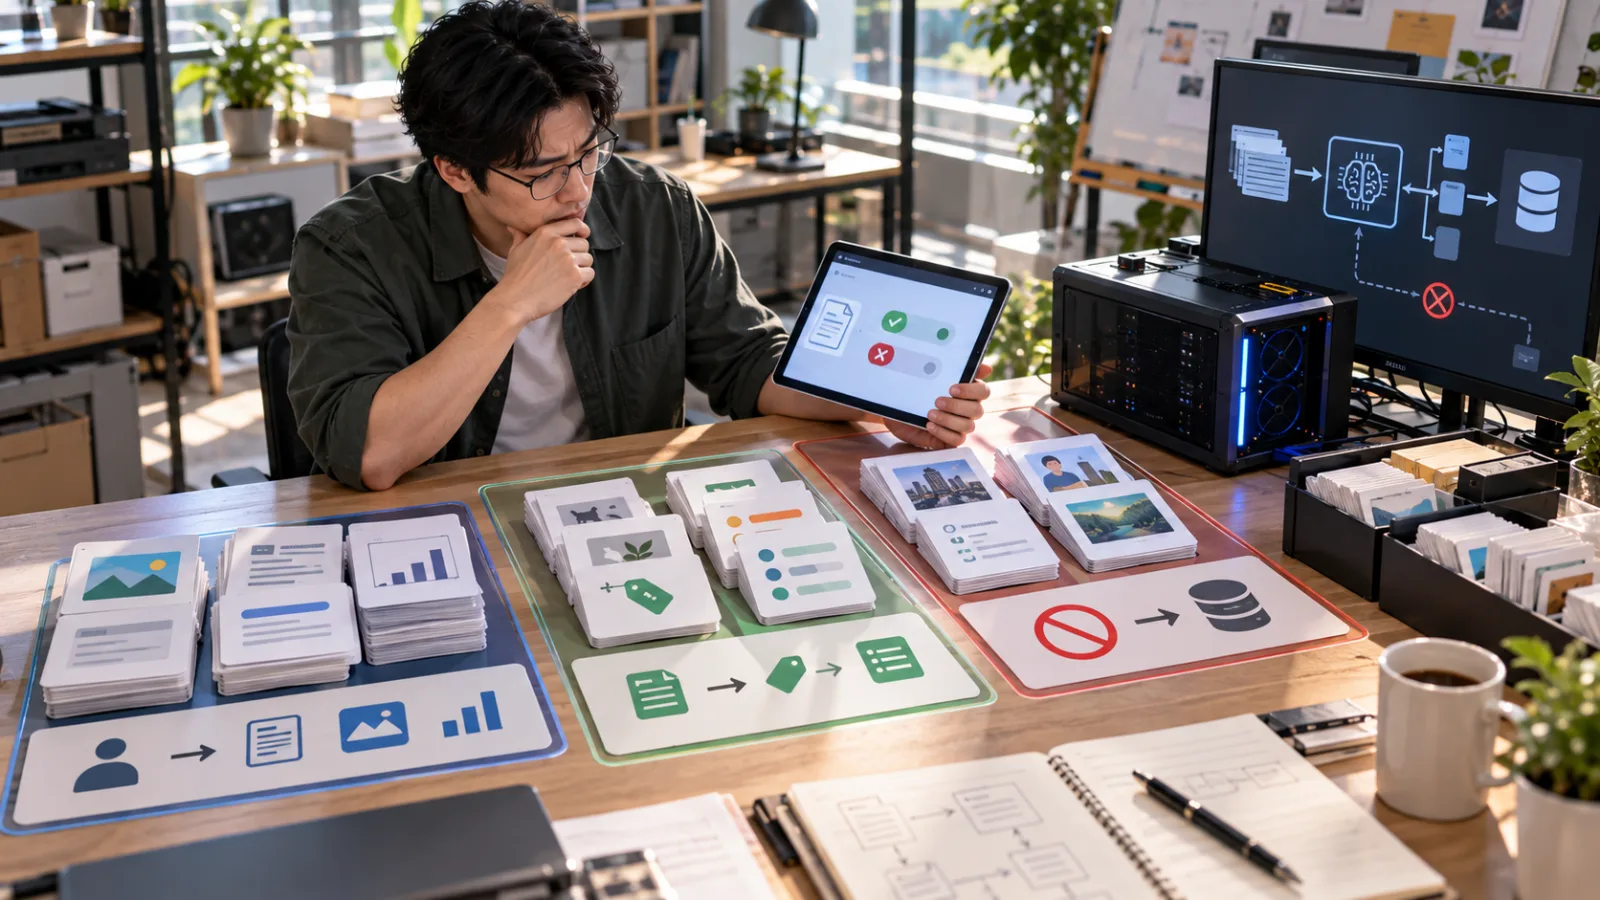
Because here, four completely different issues are mixed together:
You can access the output.
You have certain rights over the output.
The platform’s permitted ways to use the service.
And what kind of model you plan to train using that data.
Ignoring any of these layers may lead to incorrect conclusions.
What Does "The Output Is Mine" Actually Mean?
Let's start with the most confusing part.
OpenAI’s commercial terms clearly state:
Between OpenAI and the customer,
within legal boundaries,
customers retain rights to their inputs,
and own the output.
Anthropic’s commercial terms take a similar approach:
Customers own the output they generate.
So, it’s easy to jump to this conclusion:
"If it belongs to me, I can do whatever I want with it."
But that’s the problem.
Ownership and Service Usage Rules Are Different Matters
Imagine you bought a ticket to an event.
The physical ticket belongs to you.
But that doesn’t mean you can:
Make ten thousand copies,
and allow ten thousand people to enter together.
Because:
Owning something and how the service provider permits you to use it are two separate rules.
The same applies to AI output.
The platform may say:
Output, in principle, belongs to you,
but when you use the service,
you must still comply with other usage restrictions.
What Does OpenAI Currently Specify?
OpenAI’s current general terms of use explicitly prohibit:
Using output to develop models that compete with OpenAI.
The commercial service agreement aligns with this direction.
This means you cannot automatically assume, just because:
“These responses are my outputs,”
that:
“I can collect them extensively and use them to train a large model competing with OpenAI.”
This distinction reflects the difference between ownership and usage restrictions.
But OpenAI Doesn’t Completely Ban Model Training
It’s also not correct to say:
“OpenAI output can never be used for machine learning.”
Because OpenAI’s commercial service agreement lists some Permitted Exceptions.
For example, one category includes cases where the output is mainly used for:
Classification,
organizing,
and structuring data
AI models.
Such tasks include certain:
classifiers and embedding-related work.
But a key condition is that these models can’t be distributed to third parties or offered commercially.
Additionally,
using OpenAI’s own fine-tuning or model customization services
is also officially permitted.
So, the question isn’t only:
“Is there any model training?”
But rather:
“What kind of model are you training?”
Claude Follows a Similar Logic
Anthropic’s commercial terms state on one hand:
Clients own their outputs.
But on the other hand,
they restrict users from using Anthropic’s services to:
build competing products or services,
explicitly including:
training competing AI models.
Unless Anthropic grants explicit approval.
So:
Even if Claude’s answers are your output,
whether you can turn大量 Claude output into training data for another foundation model
still remains two separate questions.
Is Model Distillation Itself a Violation?
No.
This is one of the most important concepts today.
Distillation is a normal machine learning technique.
Simply put,
you can use a stronger teacher model’s output to help train a:
smaller,
cheaper,
and faster
student model.
AI companies do this themselves.
Anthropic has explicitly mentioned:
Frontier AI Lab performs distillation on its own models,
transferring large model capabilities into smaller, cheaper models.
So the real question has never been:
“Is distillation legal?”
The real question is:
“Whose output are you distilling, and do you have rights to use it this way?”
Don’t Mix Up These Three Scenarios
Scenario 1: Distilling Your Own Model
Suppose a company trains a large model themselves.
They generate synthetic data with their large model,
and then use it to train a smaller model.
As long as data, licenses, and other legal requirements are properly handled,
this is a normal development approach.
Scenario 2: Using Data Clearly Allowed for Training
For example:
You acquire a dataset whose license explicitly permits:
machine learning training,
derivative models,
and commercial use.
Then you simply follow the license rules.
The crucial detail is the authorization itself.
Just because the data is “available on the internet”
does not mean you can automatically train with it.
Scenario 3: Mass-collecting Answers from Another Company’s AI to Train a Competing Model
This is currently the most controversial point.
If platform terms prohibit:
using output to develop competing models,
then even if:
each output piece is obtained through regular API calls,
the overall usage may still violate terms.
Not to mention:
mass account creation,
circumventing rate limits,
bypassing protective measures,
and attempts to extract hidden reasoning.
These may violate additional restrictions.
The OpenAI Incident on September 30 Was a More Extreme Case
The event OpenAI revealed on September 30
wasn’t just about mass collecting final answers.
OpenAI said the incident attempted to extract:
Protected reasoning.
That is, the internal reasoning the model uses to solve problems,
which is not intended to be directly shown to users.
OpenAI refers to this behavior as:
Adversarial distillation.
This is fundamentally different from a typical user:
asking ChatGPT to produce 100 customer service examples.
OpenAI stated these operators didn’t hack the database directly.
Instead, they designed special interactions,
making the protected reasoning available in readable form.
That’s why this incident cannot be oversimplified into:
“Using AI output to train models is always illegal.”
It’s not that simple.
What If I Just Generate 1,000 Customer Service Q&A with AI?
This is a more typical scenario many companies might face.
For example, if you want to build:
your own FAQ classifier,
you might first ask AI to generate many examples covering:
refunds,
shipping,
payments,
accounts,
and product issues.
Then you use this data to train an internal classification model.
In this case, don’t just consider:
“This came from AI.”
You need to confirm first:
1. Does the platform’s current terms allow this kind of use?
2. Are you training a general classifier or a competing generative model?
3. Will this model be used only internally or sold externally?
4. Are you using official APIs or fine-tuning processes?
5. Does the training data include any third-party copyrights, personal data, or confidential info?
The answer changes depending on the situation.
“Not a Competing Model” Isn’t a Free Pass Either
Another common misconception is:
“My model can’t compete with OpenAI’s, so it’s not a competing model.”
You cannot rely on that judgment alone.
Because platform terms may restrict not only:
competing models,
but also:
mass automated output extraction,
rate limit evasion,
safety mechanism bypassing,
reverse engineering,
or other data acquisition methods.
So before building a training pipeline,
don’t only check the final model name.
You must verify:
how the data was obtained.
Can I Just Paste ChatGPT’s Answers into My Own Documents?
This is a completely different matter.
Using output to:
compile reports,
rewrite marketing copy,
include in presentations,
create internal SOPs,
write code,
or perform analysis
is very different from:
mass producing synthetic training datasets.
Platforms generally permit normal content use,
but that doesn’t automatically extend to a:
foundation model training license.
That’s why:
“Output can be used commercially”
doesn’t equal
“Output can be used for training another AI.”
Third-Party Rights Are Another Consideration
Even if the platform permits certain uses,
don’t forget that AI outputs may include rights of others, such as:
copyrighted content,
brands,
personal data,
trade secrets,
or restricted datasets.
The platform granting you ownership of output
doesn’t mean it can eliminate:
all third-party rights.
So “the platform says the output is yours”
is not a universal legal pass.
Simple Guidelines for Most People
Next time you plan to use AI output to train a model,
don’t just ask:
“Is this output mine?”
Also ask five other questions:
- Which product and terms version am I using right now?
- Do the terms specifically restrict model training or competing models?
- Am I using official fine-tuning, or am I extracting output extensively myself?
- Am I training an internal classification tool or a general generative model?
- Does the training data include third-party content, personal data, or confidential info?
Answering these questions will get you closer to the real answer.
So What’s the Bottom Line?
ChatGPT or Claude responses are your output, but that doesn’t automatically grant unlimited rights to train any other AI model with them.
You must distinguish clearly between:
output ownership
and
service usage permissions.
Model distillation is a normal technique.
The question never is:
“Is there distillation?”
But rather:
Who is your teacher model?
Where does your training data come from?
What do terms allow you to do?
These three factors determine if you can proceed.
Platform terms can also change.
If you're seriously planning a commercial training pipeline, confirm the latest applicable terms for your account, plan, and product instead of relying solely on any single news summary.
Recommended Reading
AI Q&A | 2026/07/15: Can AI-Generated Articles and Images Be Used Commercially?